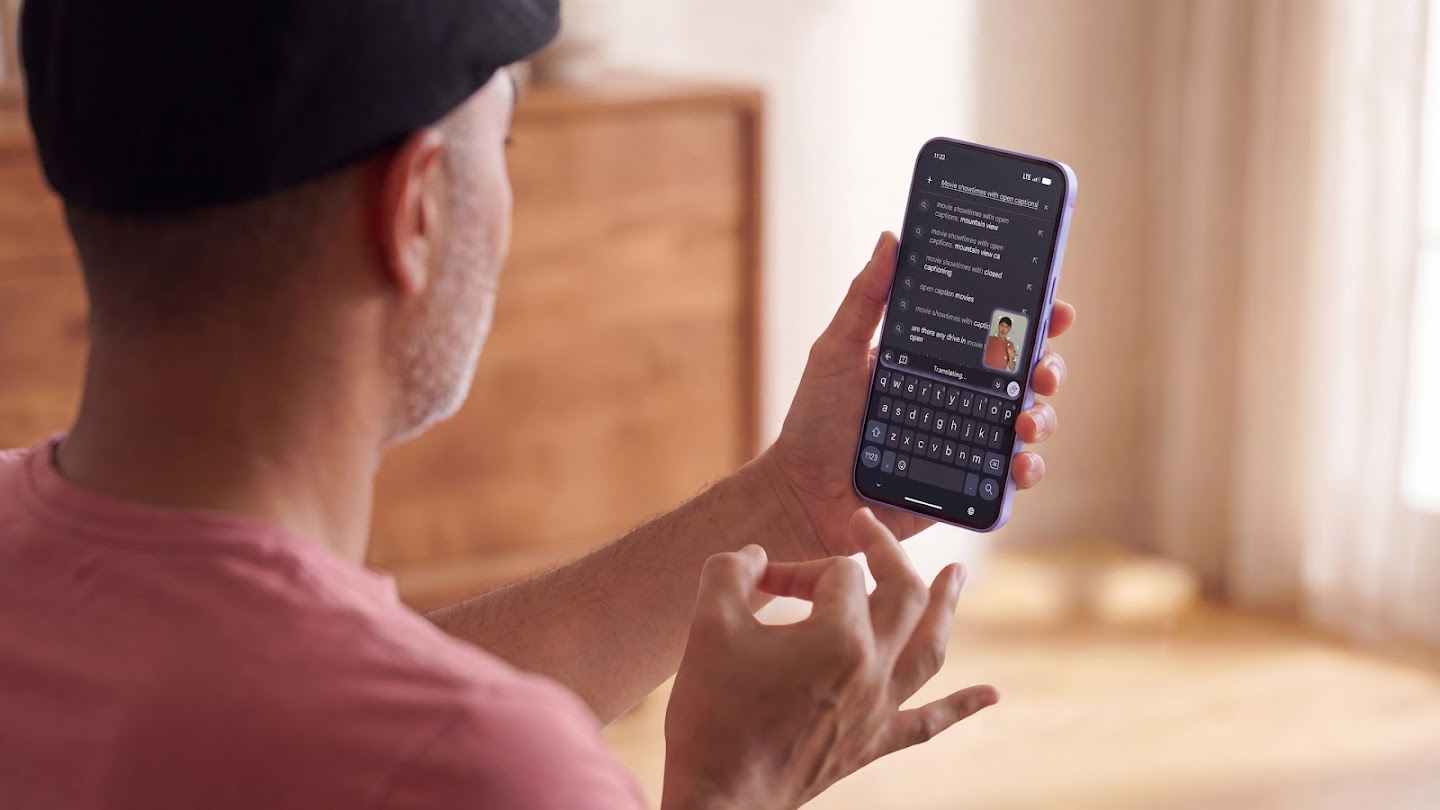
Pixel 11 can now turn American Sign Language into English text wherever a person would normally type. Google has placed its sign-language-to-text model, SL2T, inside Gboard and Live Transcribe, so a user can sign a search, draft a message, ask Gemini a question, or respond during a conversation.
This is a narrow launch, not universal sign-language translation. It starts with ASL-to-English on one phone family. But it makes several design choices unusually visible: sign language is treated as a complete language, the model reads whole-body movement, raw camera video does not go to the translation server, and Deaf people helped shape the product from the beginning.
From a lab model to a phone input method
Sign language is not a word-by-word hand code
Spoken-language transcription maps sound into text in the same language. Sign-language translation is different. Sign languages have their own grammars and vocabularies, and meaning can arrive simultaneously through the hands, arms, torso, head, and face.
That is why systems built around gloves or isolated hand shapes miss important information. SL2T first converts a signer’s movement into pose landmarks, then translates the sequence directly into text rather than passing through a fixed list of gloss labels. Google says this direct route avoids an artificial vocabulary ceiling and preserves more of the spatial and non-manual structure of signing.
The company trained SL2T on more than 100,000 hours of data across over 50 sign languages, with roughly one quarter of the data in ASL. Training across languages is part of the research strategy, but the shipped product supports only ASL-to-English for now. More devices and languages are planned, without a public schedule.
The raw video stays off the translation server
The privacy boundary is concrete. MediaPipe Holistic runs on the phone and tracks geometric points on the signer. Only those coordinates are sent to Google’s server for translation. The original camera video can be discarded immediately, according to Google.
That does not make the system fully on-device: pose coordinates still leave the phone, and the translation itself happens on a server. It does mean the product does not need to upload a recognizable video of the person signing. The distinction is useful whenever a camera-based AI feature claims to protect privacy: ask what is extracted locally, what crosses the network, and what is retained.
Google reports a zero-shot score of 70 BLEURT on the FLEURS-ASL sd-test, which it says is higher than previously reported results. That is a maker-reported benchmark, not a guarantee for every signer or sentence. The team’s usability work is more revealing. It specifically tested latency, false output when nobody is signing, left-handed signing, and one-handed signing while the other hand holds a phone.
Built with the community, and still incomplete
Google says the project was conceived by Sam Sepah, a Deaf Googler. Deaf partners participated in data collection, Deaf users evaluated the system, and an AI Sign Language Advisory Committee helped assess impact. The company and committee also published a joint impact report for the release.
That process does not erase product limits. The article documents translation errors, and the first release covers one language pair despite more than 200 sign languages worldwide. Signers also differ by dialect, fluency, physical ability, handedness, and context. A strong benchmark average cannot stand in for all of those experiences.
The meaningful change is therefore not that AI has “solved” sign language. It is that an affected community helped move one translation system into an everyday input surface, with its data path and limitations open enough to examine.
Three more developments worth knowing
Gemini 3.7 Flash arrives with temporary pricing
Google released Gemini 3.7 Flash across the Gemini API, Google Antigravity, Android Studio, Gemini Enterprise, and Gemini Spark. The company positions it as a faster workhorse for coding, web development, document analysis, and automation.
Google reports higher results than Gemini 3.6 Flash on FrontierCode, DeepSWE, WebDev Arena, GDP.pdf, and AutomationBench. Those are company-selected comparisons and do not predict performance on every project. The availability and price are firmer facts: introductory API pricing is $0.75 per million input tokens and $3.75 per million output tokens through December 31, 2026. Starting January 1, those prices rise to $1.50 and $7.50.
For students and small builders, the date matters as much as the benchmark. A prototype that is affordable during an introductory period may have a different operating cost when the permanent price begins.
Most surveyed parents were not intensive GenAI users
An open-access study in Computers in Human Behavior: Artificial Humans surveyed 457 German-speaking parents and caregivers of children in grades 3–6 in Switzerland. It separated generative-AI use for parenting questions from use for child-health information.
Intensive use was uncommon: 4.8% for parenting and 8.1% for child health. Parents’ general attitudes toward AI were the most consistent correlate of use, while AI-literacy beliefs and family-need measures showed weaker or more selective relationships.
This was a cross-sectional online survey, so it cannot show that attitudes caused use. It also should not be generalized to all families, countries, languages, or child ages. Its value is more modest: it challenges the assumption that chatbots have already become a routine parenting adviser for most families in the sample.
The EU clarified a technical marking deadline
Regulation (EU) 2026/1744 gives providers of generative-AI systems placed on the market before August 2, 2026 until December 2, 2026 to comply with Article 50(2) marking duties. The rule concerns machine-readable marking of synthetic audio, image, video, and text outputs, with EU-level codes of practice meant to support detection, marking, and labeling.
The wording is easy to oversimplify. This is not a blanket instruction that every person must put a visible “made with AI” label on every social post. It is a provider obligation about making generated outputs detectable in a machine-readable form, with separate transparency rules applying in other contexts.
For families and creators, the practical signal is that synthetic-media provenance is moving from voluntary product behavior toward regulated infrastructure. The next useful evidence will be how providers implement the mark, which tools can read it, and whether the signal survives ordinary editing and reposting.
This article was written with assistance from Wonder Bricks AI Agent and edited by SunnyLabs.