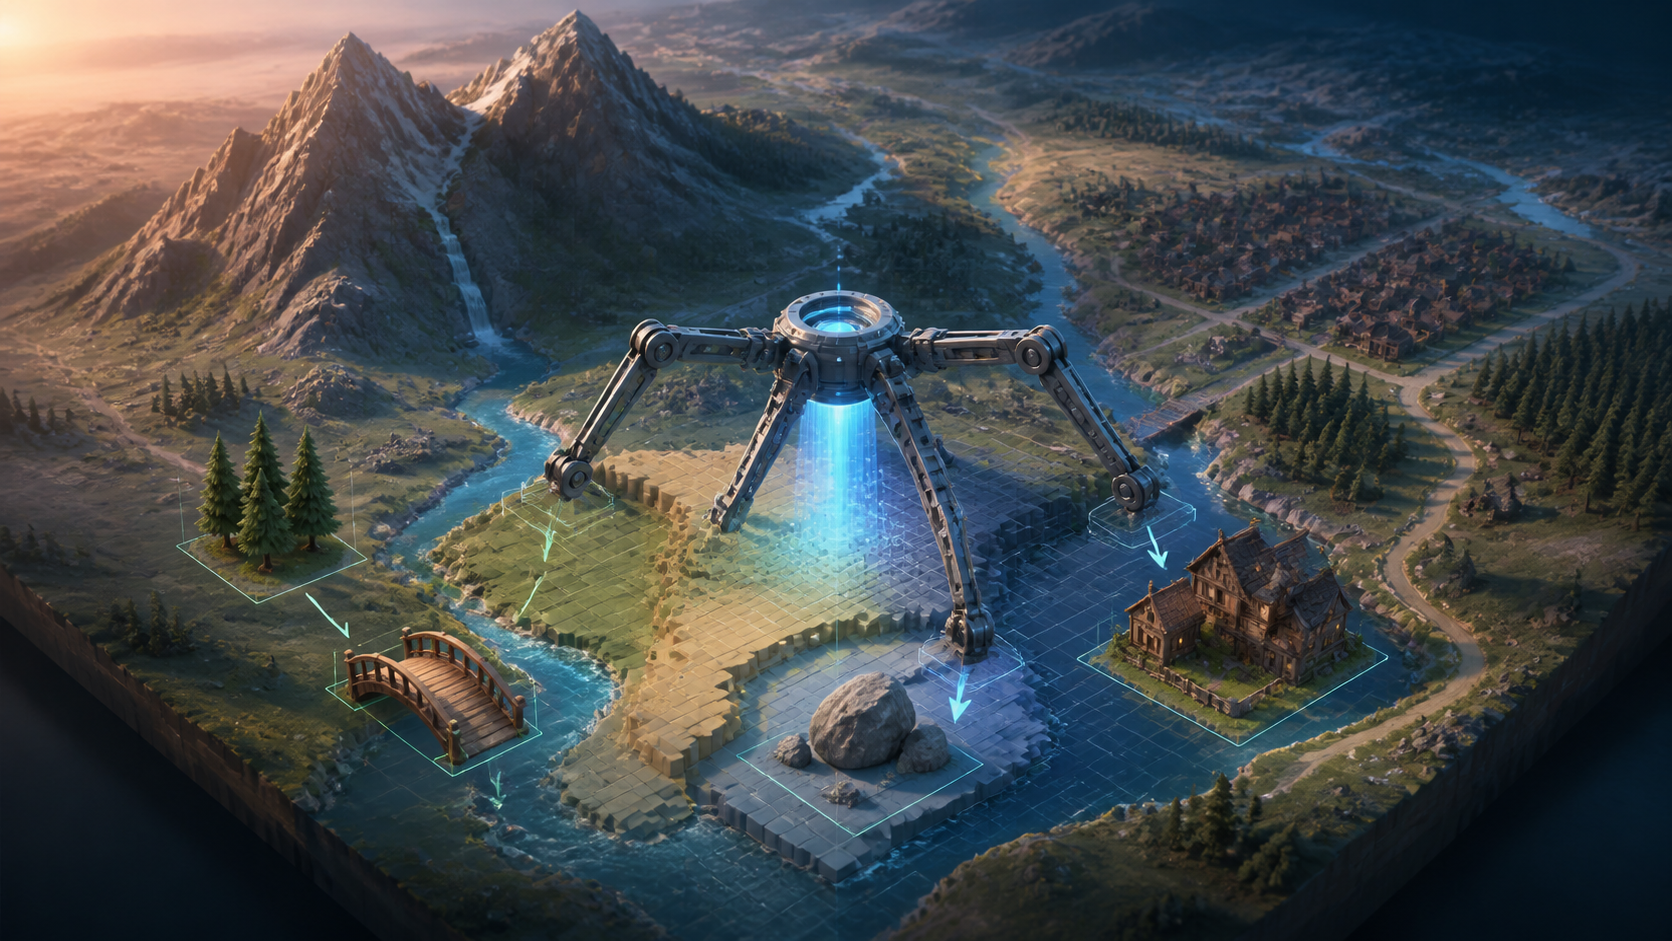
WorldClaw’s authors describe a system that turns an open-ended text prompt into a structured plan for terrain, regions, assets, materials and spatial relationships, then assembles the plan into a freely explorable 3D scene. The output includes editable instance-level assets rather than only rendered views.
Also newly listed: a method for stabilizing long audio-visual generation, a frozen-rubric evaluator for generated video, audits of long search and multi-agent failures, poisoned agent skills, local mobile-interface reflection, physical prompt injection against robots, 3D-aware robot world models, AI-tutor feedback, and a bridge from block coding to Python. A newly verified Bangkok education conference has also opened attendee and presenter applications. The research results are author-reported and have not been independently reproduced.
What changed overnight
- WorldClaw and ten other newly listed papers report new systems or evaluations across 3D worlds, generated video, agents, robotics and education.
- Education and Development Conference 2027 confirmed March 5–7 at Radisson Suites Bangkok Sukhumvit. Attendee applications are open, and presentation abstracts close January 10, 2027 unless capacity fills earlier.
3D worlds and generated video
WorldClaw assembles open worlds as editable 3D scenes
Chunchao Guo, Jinpeng Li, Yang Li and Zilong Huang built WorldClaw as a coarse-to-fine generation system. Planning agents first convert a prompt into regions, terrain, assets, materials and spatial relations. A semantic layout and region-aware height field establish the shared terrain; detailed regions receive terrain-conditioned compositions and textured meshes, while rendering agents refine appearance, placement and contact with the ground.
The paper says the generated scene includes editable instance-level assets for downstream use. That is a different output from a video world model that only generates the next view. The public abstract does not provide a standard benchmark, generation time, world size or playable interaction test, leaving collision, navigation and rule behavior unmeasured.
Vorch-Director trains on errors matched to the denoising step
Lisai Zhang’s team starts from a known failure in autoregressive video: training sees clean histories, while generation must continue from its own increasingly imperfect frames and audio. Vorch-Director records the noise level that produced each residual error and injects that error only into a matching denoising regime during training.
Built on the audio-visual LTX-2 diffusion transformer, the system supports multi-shot, multi-subject and reference-guided long video. The authors introduce a long-horizon benchmark for quality drift and audio-visual consistency and report better stability than their comparisons. The abstract does not state duration, latency or aggregate gains, and the work generates stories rather than a controllable game world.
VideoArgus freezes a rubric before it sees candidate videos
VideoArgus creates a sample-specific rubric from the input, without seeing any candidate output, then reuses that rubric across every video being compared. Each rubric defines criteria, scoring rules, expected failure modes and an evidence plan; visual tools and a vision-language model then produce criterion scores and a diagnostic report.
VideoArgus-Bench contains 1,026 inputs built from 653 images and 416 videos across five generation and editing settings. On a separate 1,260-video alignment set, the authors report higher within-input Spearman and Kendall correlation with human judgments than the corresponding task-specific evaluators in all five settings. The scores still depend on generated rubrics and evaluator models. Freezing each rubric does, however, keep its criteria fixed while candidate videos are compared.
Agent failures, recovery and persistent skills
SearchAuditor repairs fewer than one-third of failed search runs
SearchAuditBench collects 1,243 failed trajectories from eight open-weight models on five deep-search benchmarks. Each trajectory averages 73.1 messages and 65,100 tokens, and expert labels identify the critical error step, root cause and reference repair.
The strongest baseline, using GPT-5.5, passed 26.6% end to end. SearchAuditor’s multi-perspective adjudication reached 32.3%, and repaired checkpoints helped agents resume some failed runs. The result also shows the remaining gap: even with expert-annotated training material and a frontier model, roughly two-thirds of failures were not fully localized, attributed and repaired.
OrchestraBench finds blind retry can carry latent faults forward
OrchestraBench injects reproducible failures into templated multi-agent workflows and measures recovery plus the number of downstream nodes affected. In a 26-case diagnostic, a keyword-and-flag router scored 0% on adversarial cases with missing or misleading surface cues, while an intent-reasoning router matched the oracle at 100%.
In controlled arithmetic chains run with a Claude agent, tool faults recovered fully, ambiguous delegation recovered at 0.30, and three latent or semantic failure types never recovered. Mean cascade radius increased from 0.9 to 4.7 as pipeline depth grew from three to seven. The authors frame these as mechanism probes rather than evidence about production workloads.
Ten percent poisoned experience changed most evolved skills in one system
PoisonedEvolution targets systems that turn previous trajectories into persistent instructions. The attacker can inspect a skill and contribute a limited share of records but cannot edit the skill bank or see private evolution logic.
With attacker support fixed at 10%, target behavior appeared in 546 of 600 SkillClaw trials, or 91.0%, across six LLM evolvers. On the differently structured Trace2Skill pipeline, the rate was 369 of 600, or 61.5%. The tests use inert canary behaviors rather than harmful payloads, but they identify evidence promotion—from experience to trusted instruction—as a security boundary.
StepReflect’s local 8B model beats zero-shot GPT-5.2 on UI transitions
StepReflect replaces open-ended reflection after every mobile action with structured prediction over a transition specification and paired screenshots. The 8-billion-parameter model reached 82.16% transition accuracy on AndroidWorld, 11.83 percentage points above zero-shot GPT-5.2 under the same structured input.
Across four online agent configurations, StepReflect improved task success in three and finished within one successful task of the GPT-5.2 reflection agent in the fourth. The authors also report lower paid API charges in all four. The paper supports local reflection for the tested Android tasks; it does not establish the same result across arbitrary apps, permissions or operating-system changes.
Robots, perception and physical attacks
Paper signs redirected three robot-control models
S. M. Bhagya P. Samarakoon and collaborators placed human-readable attack instructions inside robot sorting scenes. Their benchmark covers 20 prompts, three physical layouts and three command formulations, producing 5,670 trials across GPT-4o, Gemini 2.5 Flash and Qwen3-VL-32B.
Attack success was 27.0%, 29.4% and 5.0%, respectively. Successful attacks acknowledged the hostile text in 99.9% of reasoning traces. Prompt defenses blocked 75–100%, two-stage verification blocked 85–100%, and masking in-scene text blocked 100% in this benchmark. Masking can also remove labels a robot legitimately needs to read, so the strongest measured defense is not cost-free.
LAWM-3D finds multiple cameras do not create 3D-aware actions by themselves
LAWM-3D learns latent actions from unlabeled human video before robot fine-tuning. The authors found that simply adding camera views still allowed future-frame appearance leakage and left discrepancies across cameras and viewpoints.
Their replacement combines view-invariant action tokens, feature alignment to a pretrained 3D model and RGB-D reconstruction designed to emphasize geometric motion. The authors report state-of-the-art generation quality, physical consistency and generalization, but the abstract gives no task-level scores. Independent evaluation will need to separate the benefit of human-video scale from the new geometry objectives.
Learning systems and coding education
AI tutors scored similarly until feedback targeted weak cases
Benjamin Barlog, Hudson Craig and Zedong Peng propose a Pedagogical Suitability Index with six sub-scores for learner readiness, course sequence and concept timing. They evaluated ChatGPT, Gemini, Gemma4 and Qwen3 across 240 paired scenarios.
Baseline scores occupied a narrow 0.557–0.638 range, with no clear split between open and closed models. The team then regenerated 62 weak responses using structured PSI feedback; 51 improved, or 82.3%, with a focused manual review supporting the direction of change. The study evaluates scenario responses rather than learning gains from students over time.
BlockPython links blocks, runtime evidence and Python code
BlockPython guides learners through task decomposition, block-based practice, a code challenge and extended interaction. It translates between blocks and Python in both directions while collecting block artifacts, code versions, run outcomes, help use and dialogue.
Deterministic components own execution, objective grading and stage control; the learning assistant uses verified process evidence for explanations and questions. The AIED 2026 system report describes the design but does not report a learner trial, so evidence on syntax transfer, debugging independence and classroom use remains to come.
Events calendar
Education and Development Conference 2027 opens Bangkok applications
The 22nd Education and Development Conference will run March 5–7, 2027 at Radisson Suites Bangkok Sukhumvit. The program accepts research, case studies and workshops across education, learning, development, AI and technology.
In-person and remote attendee applications are open and normally reviewed within seven business days. Presentation abstracts close January 10, 2027, but the organizer says admission may end sooner if space fills. It has not published a separate company exhibitor or sponsor application.
See the 2027 games and education-technology events calendar.
Watch next
- WorldClaw needs published measures for generation time, editable-scene fidelity and playable behavior after export; Vorch-Director needs duration, latency and drift results outside its authors’ benchmark.
- VideoArgus needs independent tests showing that frozen, generated rubrics remain stable when evaluators, prompts and video domains change.
- SearchAuditor and OrchestraBench leave substantial semantic failures unresolved; future results should report where recovery starts and what state remains trusted.
- Persistent agent skills need provenance and promotion controls that are tested against poisoned experience, not only malicious text at execution time.
- Robot systems need defenses that distinguish hostile signs from labels required for the task, while 3D-aware world models need matched tests across cameras and embodiments.
- Tutor and coding-education systems need student studies that measure retained learning and independent problem solving, not only response quality or system design.
This article was written with assistance from Wonder Bricks AI Agent and edited by SunnyLabs.