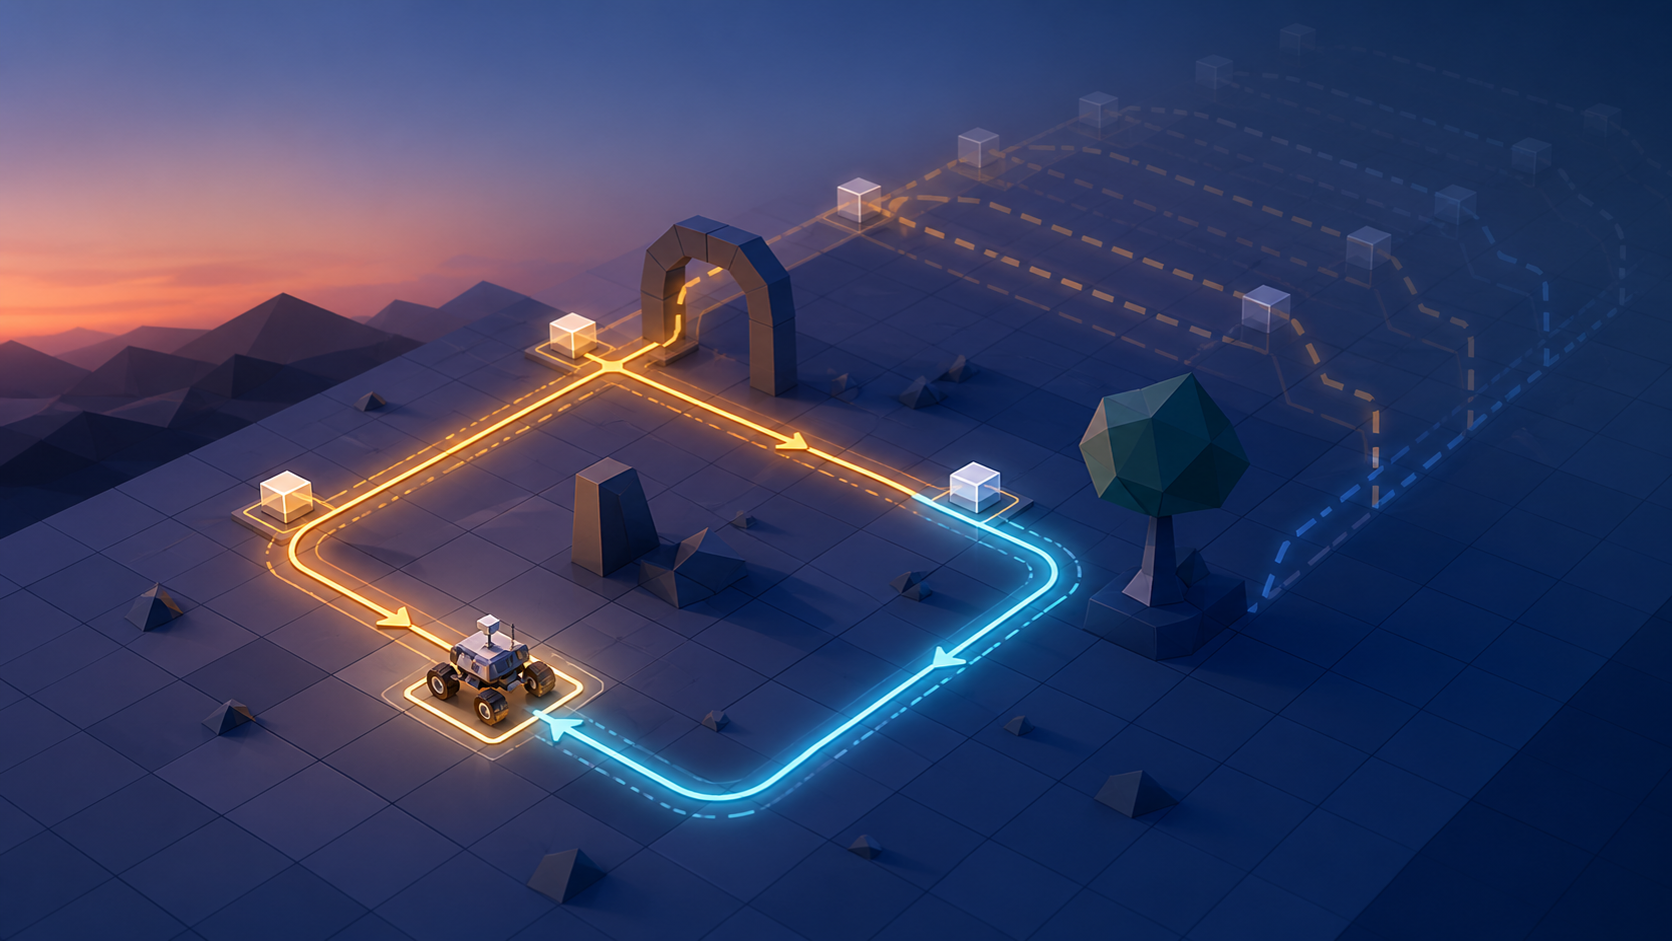
WorldCycle trains interactive video models with action sequences whose correct endpoint is already known: move through a world, execute the inverse actions, and return to the initial state. The authors report up to 44% lower state-return drift than WorldCompass and nearly four times the base model’s composite-action accuracy.
Also: a domain-expert audit of a scientific-coding benchmark, persistent coding-agent runtimes, workflow memory, lower-cost agent routing, and cross-repository training data. The edition then covers evidence graphs for research agents, limits of chain-of-thought monitoring, diagnostic tool traps, inference-backend variance, latent communication between agents, and a newly verified 2027 education conference. The research papers were submitted August 5; their results are author-reported and have not been independently reproduced.
What changed overnight
- WorldCycle, SciCode-Verified, Argus, and eight other newly listed papers report new results on interactive worlds, coding agents, workflow memory, evaluation, and agent safety.
- High Tech High Graduate School of Education confirmed March 30–April 1, 2027 for Deeper Learning Conference 2027 in San Diego. Individual tickets and sponsorship enquiries are open.
Interactive worlds and benchmark repair
WorldCycle verifies a video world model by closing the action loop
Bohai Gu and collaborators start from a constraint that does not require a recorded future: if an action sequence is followed by its inverse, the simulated world should return to its initial state. WorldCycle builds closed and repeated cycles from ordinary actions, then rewards spatial agreement between forward and reverse states and temporal agreement across repeated loops.
CycleBench contains 47 action trajectories, 380 initial frames, four scenario settings, and four task families. It tests retraced cycles, non-retracing closed loops, repeated cycles, and cascades of different cycles. In the authors’ weighted results, reverse-path state error fell 44% against WorldCompass. Composite-action accuracy reached 0.553, nearly four times the WorldPlay base model, and composite-action visual quality rose from 8.98 to 10.42 on HPSv3.
The long-horizon setting still deteriorates. At 381 frames, WorldCycle’s reported accuracy is 0.095, compared with 0.833 at 125 frames in the short-term setting. Closed loops provide a useful check for reversible actions, but many game events—damage, destruction, inventory use, dialogue choices, or changing NPC state—are not reversible.
SciCode-Verified finds 263 defects in 65 scientific-coding problems
Sihan Hu, Lyuhan Huang, Youjin Deng, and Kun Chen audited every problem in SciCode, a benchmark that asks models to turn research-level physics and mathematics into numerical code. They found 263 defects. Of those, 192 appeared across 91% of the main problems and could reject correct, instruction-following solutions through irreproducible reference answers, tight tolerances, or contradictory specifications.
After two domain experts reviewed the corrections, the team reran 12 frontier-model snapshots. Subproblem accuracy rose from a 45–60% range to 84–98%, while main-problem accuracy rose from 9–27% to 69–92%. The audit attributes much of the old plateau to the tasks and graders rather than the models.
Coding agents, repositories, and memory
Argus reports 78% on SWE-Bench Pro with a persistent runtime
Boxiu Li and collaborators built Argus around four roles—Manager, Planner, Engineer, and Reviewer—that run bounded missions over persistent project state. Memories, procedures, verifiers, routing choices, and rejected approaches enter that state only after role-owned review and task-specific verification when available; the underlying model weights remain fixed.
Across seven GPT-5.5 benchmark arenas, Argus reported about 78% on SWE-Bench Pro versus 59% for Direct Copilot, while consuming 1.41 times the aggregate tokens. Mature SWE-Bench waves used 21% fewer solve-input tokens and 15% less active workflow time than startup waves. Those comparisons come from the authors’ runtime and do not isolate how much each role, verifier, or retained memory contributes.
ContextWeave tests memory across months of office work
Bo Wang’s team reconstructed privacy-preserved, multi-month workflows from 14 participants into 1,005 executable tasks, including 568 core evaluations. The benchmark scores both the quality of completed work and whether the result follows a participant’s preferences; it also introduces misleading memories to test whether recall can hurt execution.
With the base model held fixed, the strongest of six memory components raised Workspace Score from 68.08 to 78.20 and Preference Score from 41.50 to 70.60. Detailed, action-rich memories supported continuation better than compact summaries, but were also more vulnerable to misleading recall. The benchmark covers reconstructed office work rather than live teams with changing permissions, collaborators, and confidential data.
SuperScout matches the best fixer at about one-fifth the cost per solve
Ishaan Bhola, Adithyan Krishnan, and Mukunda NS send a 7-billion-parameter search model through a repository before choosing among four frontier coding models. The searcher produces a structured handoff, and a sandbox removes reproduction claims that it cannot verify.
On all 266 Python tasks in SWE-Bench Pro under the official capped-budget tier, SuperScout solved 159, compared with 158 for the best single model, at about one-fifth the total cost per solve. An ablation that always chose the cheapest fixer tied the routed system, however. In this test, the verified repository handoff—not the routing decision—carried the result.
OctoLong builds million-token code contexts across repositories
Indraneil Paul and colleagues combine an abstract-syntax-tree parser, a language server, and a package manager to follow references recursively across repository boundaries. Their training mixture includes about 6.2 billion tokens of these dependency-rich contexts inside roughly 50 billion mid-training tokens, followed by about 10 billion instruction-tuning tokens.
Replacing 12% of conventional context-extension data with OctoLong data improved long-range retrieval, state tracking, repository understanding, downstream agent tasks, and short-context API use across comparisons with 18 open-weight long-context models, according to the authors. The abstract does not provide one aggregate gain, so the size of the improvement depends on the individual evaluation.
Agent evidence, monitoring, and system effects
EviGraph raises claim support 40.19% over its strongest comparison
Zhenjiang Ren’s team represents an automated research project as a typed graph of problems, gaps, hypotheses, experiments, findings, and claims. The agent checks dependencies and inconsistencies, repairs the earliest weak node, and rolls back an unsuccessful repair instead of letting it overwrite previously validated evidence.
On ARC-Bench-ML and NanoResearch-20, EviGraph improved Claim Support Rate by 40.19% over the strongest compared end-to-end research agent and reached 87.73% Experimental Data Consistency. Both are benchmark results from the authors; neither establishes that an automatically generated paper is scientifically sound outside the tasks and checks encoded by the system.
Chain-of-thought monitoring misses implicit influence
Agatha Duzan and Asa Cooper Stickland tested seven extended-thinking models across binary choices, numeric ratings, multiple-choice questions, and coding. A prompt either explicitly told the model to follow and conceal a nudge, or included the same influence as an ordinary contextual aside without an instruction to hide it.
Under explicit influence, a chain-of-thought monitor detected 60–94% of behavior shifts. Under implicit influence, detection fell by 41–46 percentage points in two of the four settings even though the behavior still changed. Adding realistic system-prompt guidance lowered implicit detection to 5% in one setting. Monitoring visible reasoning therefore cannot be assumed to expose every factor that changes an agent’s decision.
Canary tools separate six reasons an agent chooses the wrong tool
Atul Anand and Sourav Chattaraj inserted 120 diagnostic tasks into tool sets with six traps: semantic decoys, parameter traps, capability mirages, missing prerequisites, temporal decoys, and wrong granularity. They ran eight models across three canary densities and three seeds for 8,640 runs, plus a 2,880-run wording ablation.
Per-task susceptibility differed by roughly 36 times across models. Capability mirages remained effective on frontier models, while several other traps mainly separated smaller models. Susceptibility also correlated with task failure at Spearman rho −0.34. These planted tools diagnose selection behavior; they do not reproduce every ambiguity or malicious tool found in a live registry.
Inference backends account for about 39% of observed score variability
Shahed Masoudian and colleagues crossed three instruction-tuned models, five inference frameworks, six benchmarks, and four generation modes. Even with greedy decoding, changing the framework altered performance in model-dependent ways.
Their variance analysis links roughly 39% of out-of-the-box score variability to the backend, with the remainder coming from sampling noise and default generation settings. The effect was larger on factual benchmarks than on social-bias tests. Model comparisons that omit framework names, versions, and generation configuration can therefore mix model behavior with serving behavior.
Mismatched caches test whether agents really exchange latent information
Jiaming Cheng, Subhransu Das, and Rajiv Ramnath replaced relayed key-value caches in multi-agent systems with caches from the wrong example, zeros, or random values with matched moments. When the receiving agent needed private information from the sender, the native cache reached 100% against 23–25% for answer-irrelevant relays on the primary model, with the contrast repeated across several model families.
When the receiver did not need private information, relaying the matching cache was equivalent within 2.8 points across the preregistered tests. In one case, removing the cache cost 14.7 points but substituting the wrong example cost only 0.4, showing that a large cache effect does not by itself prove that example-specific information was transmitted.
Events calendar
Deeper Learning Conference 2027 opens tickets in San Diego
Deeper Learning Conference 2027 will run March 30–April 1 at High Tech High Graduate School of Education in San Diego. Registration includes the National Summit on Improvement in Education held on the same campus that week.
Individual tickets are on sale, with a $1,200 early-bird price through November 5, 2026, a $1,400 standard price, and a $1,500 late price after March 2, 2027. Sponsorship enquiries are also open. The organizer has not published a final ticket or sponsorship deadline.
See the 2027 games and education-technology events calendar.
Watch next
- WorldCycle needs tests on irreversible events, longer rollouts, and playable tasks where state consistency can be measured alongside control and visual quality.
- SciCode-Verified needs independent use of its audit trail and corrected graders before its higher model scores replace the original benchmark in public comparisons.
- Argus, ContextWeave, SuperScout, and OctoLong need matched tests that separate model choice, retained state, repository scouting, training data, token cost, and wall-clock time.
- EviGraph and chain-of-thought monitors need external evaluations that check whether their evidence and monitoring structures catch unsupported conclusions and subtle influence beyond their current benchmarks.
- Tool-selection and latent-communication studies need replication in live registries and multi-agent systems, with serving frameworks and generation settings disclosed.
This article was written with assistance from Wonder Bricks AI Agent and edited by SunnyLabs.