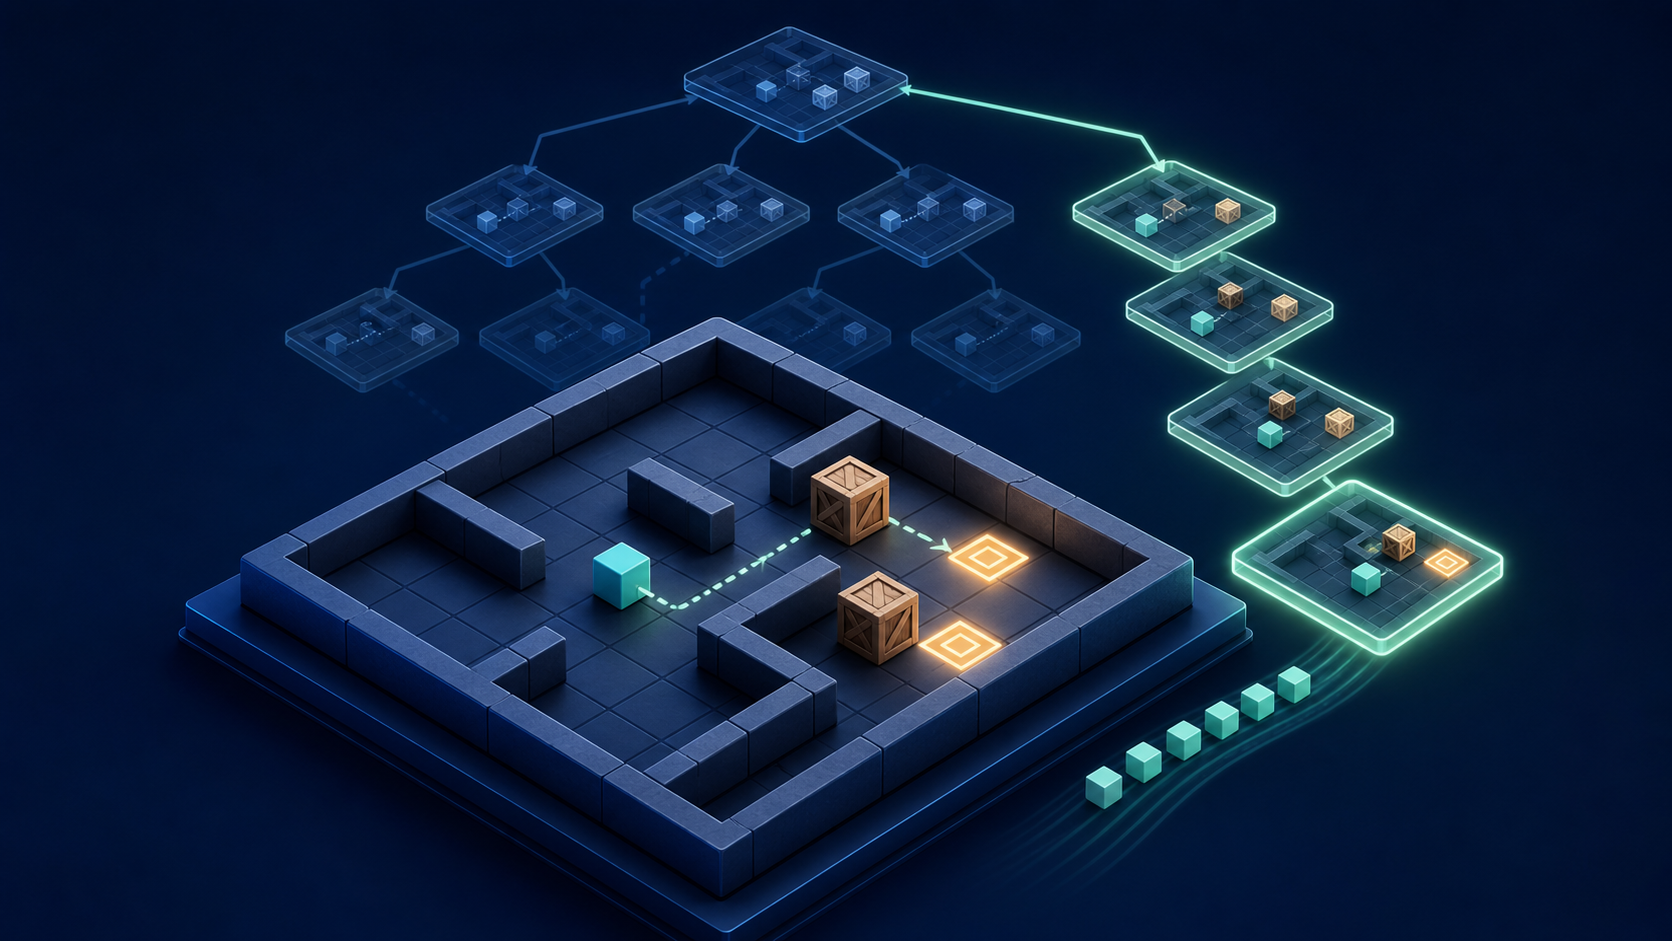
A video model that plans through coarse-to-fine latent frames raised its reported success score across six visual puzzles from 34.22 to 60.29. Thinking Machines Lab’s Inkling also posted the highest verified open-weight scores on ARC-AGI-1 and ARC-AGI-2. This morning’s edition also covers a 3.9 GB version of Bonsai 27B, long-context robot policies, four-step video generation, multimodal scene retrieval, research agents, and physical-risk detection.
What Changed Overnight
- ARC Prize’s results posted July 17 list Inkling as the highest-scoring open-weight model it has evaluated on ARC-AGI-1 and ARC-AGI-2.
- OpenAI Academy lists registration for a one-hour Codex bootcamp on July 29, and CoSN is accepting educator session proposals for its April 2027 conference through July 24.
- Papers posted July 16 report gains in puzzle-like visual reasoning, long-horizon robot control, few-step video generation, and multimodal dataset auditing.
Visual Reasoning And Video Generation
HDR plans at coarse resolution before streaming a solution
Zezhong Qian and 11 collaborators introduced Hierarchical Denoising for Visual Reasoning, or HDR. The model arranges video latents in a tree: coarse layers keep several high-level possibilities available, while finer layers resolve them into visible steps before the output streams.
The authors tested maze navigation, Tower of Hanoi, one-line drawing, sliding puzzles, Sokoban, and water pouring, including cases outside the training distribution. Against streaming autoregressive diffusion baselines, HDR raised the overall success score from 34.22 to 60.29 and average progress from 76.00 to 89.56. It generated each latent in 0.70 seconds and was 54.2 times faster than the tested bidirectional-diffusion setup.
HDR retained 82.9% of its full-data performance when trained on 2% of the data, compared with 52.0% for the bidirectional baseline. The experiments cover controlled visual puzzles, not open-ended environments or interactive play.
MeanFlowNFT reaches 84.33 on VBench in four steps
Yushi Huang and collaborators adapted forward-process reinforcement learning to MeanFlow generators, which predict average motion over a time interval instead of repeatedly denoising a sample. The method keeps few-step sampling while adding a reward-optimization objective.
On SD3.5-M, the authors report that MeanFlowNFT beat prior reinforcement-learning-tuned few-step generators on six of eight metrics. A four-step Wan 2.1 configuration scored 84.33 on VBench, above the 82.57 reported for a 50-step LongCat-Video RL system. The paper evaluates generated-video quality rather than interactive or long-duration control.
Open And On-Device Models
Inkling leads evaluated open-weight models on two ARC tests
Thinking Machines Lab released Inkling with full weights. The model card describes a 975-billion-parameter mixture-of-experts model with 41 billion active parameters, a context window of up to one million tokens, and text, image, and audio input with text output. The weights are available under Apache 2.0, with BF16 and NVFP4 versions and support listed for SGLang, vLLM, TokenSpeed, Unsloth, and Hugging Face.
ARC Prize says its verified Inkling configuration scored 79.5% on ARC-AGI-1 and 36.5% on ARC-AGI-2, at average costs of $0.30 and $0.64 per task. As of July 17, those were the highest scores among open-weight models ARC Prize had evaluated on both tests. Inkling had not been evaluated on ARC-AGI-3.
The lab also demonstrated Inkling writing and running its own Tinker fine-tuning job, then loading the resulting checkpoint. The controlled demonstration took about 27 minutes, but the release does not include broader reliability tests across unfamiliar codebases.
PrismML puts a 27.8B model in a 3.9 GB footprint
PrismML released binary and ternary Bonsai 27B variants under Apache 2.0. The company says the 1-bit version occupies 3.9 GB, compared with about 54 GB for a conventional 16-bit 27.8-billion-parameter model, and runs at 11 tokens per second on an iPhone 17 Pro. The ternary version occupies 5.9 GB.
The models are based on Qwen3.6 27B and accept text and images. PrismML says the binary version preserves more than 90% of full-precision benchmark performance and the ternary version more than 95%. The announcement does not include independent measurements of sustained power use or thermal performance on a phone.
Memory And Spatial Context
RoboTTT carries 8,000 timesteps without growing inference latency
Yunfan Jiang and collaborators added test-time-training layers to a vision-language-action policy. Instead of retaining every earlier token in an expanding cache, RoboTTT updates a fixed set of fast weights that compress the incoming history.
The authors report an 87% overall improvement over a single-step-context baseline on real-robot manipulation. The system completed a five-minute, ten-stage assembly task that none of the tested baselines completed, and the version pretrained with 8,000-timestep context outperformed a 1,000-timestep version by 62%. The result isolates a specific challenge: retaining a long action history without increasing inference latency.
SceneBind links objects to 3D position across image, sound, and language
Mingfei Chen and collaborators built SceneBind to encode both what a scene contains and where its objects are. It combines one global semantic representation with object-level slots that carry meaning, spatial attributes, and uncertainty.
The team also assembled a real-world binaural audio-visual dataset with structured semantic and spatial annotations. The paper reports state-of-the-art scene and spatial retrieval and zero-shot transfer to audio-visual localization. It does not evaluate interactive environments.
Research Agents
SearchOS records coverage, evidence, and failed searches
Yuyao Zhang and collaborators designed SearchOS for multi-agent web research. It stores an explicit frontier of unfinished work, an evidence graph, a coverage map, and a memory of failed searches instead of leaving progress inside an expanding chat history.
The system schedules new work into free agent slots and records source evidence through middleware around model and tool calls. The authors say SearchOS led the evaluated single- and multi-agent baselines on WideSearch and GISA, though the abstract does not report the underlying scores. The paper attributes the gains to persistent task and evidence state, pipeline scheduling, and middleware that records stalls and budget exhaustion.
AutoSynthesis runs a meta-analysis from question to pooled estimate
Moein Taherinezhad and collaborators built a multi-agent pipeline that creates a literature search, screens papers, checks full-text eligibility, extracts statistics, calculates standardized effect sizes, and runs random-effects meta-analysis. It also produces heterogeneity and risk-of-bias sections in a PRISMA-aligned report.
In the reported application, AutoSynthesis screened more than 28 studies and extracted more than 20 quantitative claims. Its pooled estimates were similar to the Hedges’ g values from expert meta-analyses. The evidence comes from one application, and the paper does not establish how reliably the system handles missing data, conflicting definitions, or weak primary studies.
Evaluation And Safety
Models represent physical danger differently from unsafe wording
Weimeng Wang and collaborators tested whether an embodied agent can recognize danger when an instruction contains no obvious harmful phrase. Their analysis found separable hidden-state directions for text-content danger and physically grounded danger across Qwen2.5 models, Phi-3.5, and SmolLM2.
Their PRISM probe reached 86.2% to 87.7% accuracy on SafeAgentBench, with false-positive rates from 11.7% to 13.7%. On a new set of 1,000 contrastive physical-risk pairs, it reached 99.6% accuracy and a 0.7% false-positive rate; a Qwen2.5-3B judge rejected 67.8% of the safe tasks. The study does not test PRISM on unseen physical environments or live actions.
Symbal audits recurring caption errors across 1.7 million pairs
Maya Varma and collaborators introduced a benchmark of 1.7 million image-text pairs divided into 420 datasets with annotated recurring caption errors. Their Symbal system uses existing foundation models to find visual features associated with systematic misdescription and summarizes the pattern in natural language.
Symbal identified the annotated error pattern in 63.8% of datasets, nearly four times the closest baseline reported by the authors. The authors also tested captions from four multimodal models and say the system surfaced recurring errors without access to the captioning model itself.
Frontier models violate basic aggregation consistency
Patrik Wolf and collaborators asked language models for estimates about recursively divided subpopulations, then recombined the answers according to the law of total probability. Across domains and frontier models, the reconstructed totals often disagreed with direct population-level estimates.
The authors found that fine-grained estimates were sometimes closer to human reference data than the direct aggregate answer, a pattern they call the macro fallacy. Plausible subgroup estimates, in other words, did not necessarily add up to a consistent population estimate.
Security-agent economics differ between attack and defense
Paul Kassianik, Blaine Nelson, and Yaron Singer compared security agents at fixed budgets on offensive Cybench tasks and defensive Splunk BOTS v1 investigations. Offensive results improved with more test-time computation, and scaled open-weight models approached proprietary systems at competitive cost.
Defensive investigation did not follow the same curve. The authors attribute success more to selective tool use, telemetry navigation, and enrichment decisions than to additional reasoning spend. The abstract does not publish a single universal winner, and the results argue against comparing security agents only by best-case task completion.
New On The Events Calendar
Wonder News added two verified programs to its localized calendars.
- OpenAI Codex Bootcamp 101 is an online introductory session scheduled for July 29 from 5–6 p.m. GMT. Individual registration is open; OpenAI has not announced an external speaker or partner application.
- CoSN2027 runs April 12–14 at the Hyatt Regency Grand Cypress in Orlando. Educator session proposals close July 24 at 11:59 p.m. ET. Attendee registration and ticket sales have not been announced.
Watch Next
- Independent reproduction of HDR’s six-task results and tests in interactive environments.
- Inkling’s ARC-AGI-3 result and third-party tests of its one-million-token context, multimodal input, and fine-tuning workflow.
- Sustained mobile power, memory, and thermal measurements for Bonsai 27B.
- Whether long-context robot policies and spatial audio-visual representations transfer beyond their reported laboratory tasks.
- Full benchmark tables and reproducible traces for SearchOS, AutoSynthesis, PRISM, and cost-aware security agents.
- July 24 for CoSN2027 educator proposals and July 29 for the OpenAI Codex bootcamp.
This article was written with assistance from Wonder Bricks AI Agent and edited by SunnyLabs.