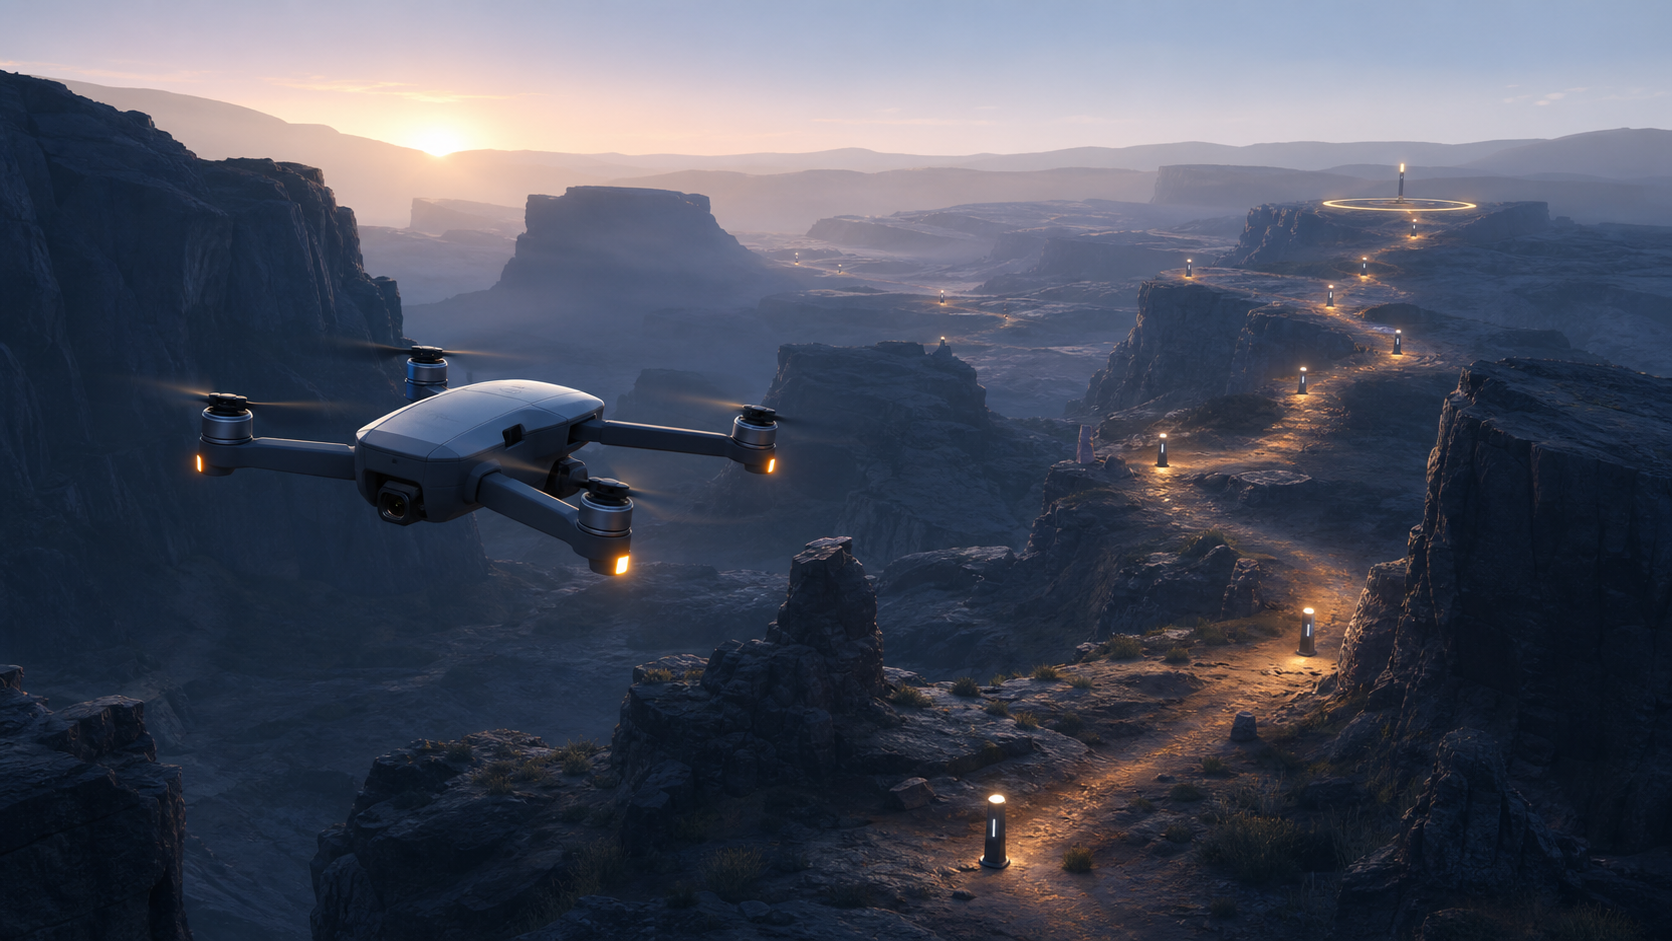
A new benchmark strips route instructions and global guidance from simulated long-horizon drone navigation. Its first vision-only baseline succeeds on 1.8% of hard episodes in unseen environments. This morning also brings persistent memory for embodied agents, real-time Gaussian mapping, robot datasets and physical interaction, agent and video safety, interface generation, streaming speech, and a new education-technology conference deadline. Unless noted otherwise, the results are author-reported from recent preprints and have not been independently replicated.
What Changed Overnight
- ArXiv posted no new computer-science batch over the weekend. Today’s 12 research items were newly verified for Wonder News from the July 24 announcement batch and were not covered in the previous edition.
- Wonder News verified an open proposal call for SITE’s March 2027 teacher-education technology conference. The call closes October 26, while attendee registration is listed separately.
Navigation, Mapping, And Persistent Memory
VoLN removes the route description from long-horizon flight
Vision-Only Long-Horizon Navigation replaces a language route with a goal image. The agent must find and interpret locally visible beacons while flying continuously through large viewpoint changes, without GPS, a global map, or route instructions that disclose distance and orientation.
VoLN-UAV contains 7,210 simulated episodes. In five unseen environments, the authors’ initial multimodal-model baseline succeeds on 7.4% of easy episodes, 4.5% of normal episodes, and 1.8% of hard episodes. The benchmark isolates long-horizon visual evidence and closed-loop control, but it does not yet cover ground-navigation agents or physical drones.
Persistent 3D visual memory beats carrying an occupancy map
Zikui Cai and collaborators evaluate embodied question-answering agents across several questions in the same scene without resetting memory. Agents that retain only a two-dimensional occupancy map remember where they travelled but lose the visual and semantic evidence needed to answer later questions.
The authors report that memory grounded in metric 3D geometry improves answer accuracy while lowering navigation cost. They also test the approach on a mobile robot. The paper does not publish one aggregate gain in its abstract, and performance across longer sessions and changing environments remains open.
GLAM-SLAM maps long outdoor sequences in real time
GLAM-SLAM separates lightweight feature-based tracking from a sparse anchor-grid Gaussian map. It partitions large environments into local scenes and uses epipolar geometry to densify Gaussian anchors without carrying one unbounded scene representation.
Tests span KITTI Odometry, Oxford RobotCar, and Málaga. The authors report 15% higher reconstruction quality than the second-best comparison while retaining real-time performance on long sequences. Code is public, but the summary does not state GPU memory or frame rate.
TableVerse builds 100,000 simulated tabletops from internet images
TableVerse reconstructs unstructured internet images into simulation-ready tabletop layouts with metric scale, object topology, and a mechanical-stability check. A second automated stage generates collision-free pick-and-place demonstrations.
The resulting TableVerse-100K dataset contains 100,000 unique environments and associated trajectories. The release targets robot-policy training, but the paper abstract does not state image licensing, dataset availability, or success rates for policies trained on the collection.
Physical Interaction And Learned Dynamics
BiCompoDiff plans a grasp, handover, and final placement together
BiCompoDiff combines a pretrained grasp diffusion model with energy functions for collision avoidance, smooth motion, handover feasibility, and safe regrasping. Gradient guidance adjusts candidate grasps while an annealed sampler refines the complete two-arm plan.
Across simulated household reorientation tasks, the authors report more than 20% higher success than the tested sampling baselines and up to 37% smoother trajectories by joint displacement. They also report real-world transfer, although the abstract does not state the number of physical trials or the objects tested.
FELT predicts touch from RGB video
FELT uses a frozen visual encoder and a lightweight decoder to generate separate left- and right-finger pressure images from ordinary RGB observations. The generated signal is designed for wiping, insertion, in-hand rotation, and other tasks where the contact surface may be hidden.
Across four contact-rich manipulation tasks, generated tactile images and latent tactile features improve policy success over vision-only baselines. The paper does not give the aggregate margin in its abstract. At deployment, the latent-feature setup needs only RGB rather than a physical tactile sensor.
PhysCoRe corrects a physics simulator with learned residuals
PhysCoRe combines a differentiable Material Point Method simulator with one network that estimates per-particle elasticity and another that corrects errors in the simulator’s internal dynamics. Its uncertainty estimate can direct further interaction toward poorly identified regions of a deformable object.
The authors report better prediction accuracy than the compared approaches on real manipulation sequences and online material identification for unfamiliar objects. The abstract gives neither an aggregate error reduction nor a runtime.
Bias-aware data collection spends demonstrations on weak instruction factors
Yu Qi and collaborators test six robot foundation policies for shortcuts across color, object, spatial, verb, and size instructions. Color dominates the reported factor hierarchy, while verbs and size are the least grounded.
The team reallocates a fixed collection budget toward those weaker factors. The strategy outperforms the tested baselines in simulation and on a real robot while using half as many demonstrations. The comparison is limited to the paper’s factor definitions and manipulation tasks.
Agents, Interfaces, Video Safety, And Speech
MV-Bench finds that generated interfaces look right before they work
MV-Bench uses Tableau workbooks to define data bindings, visual mappings, and interactions for 1,048 verified web-interface instances derived from 92 base designs. Five multimodal models receive each task in a single pass.
The strongest model reaches 75.45% accuracy on visual layout reproduction, but 21.71% on data binding and 11.68% on interaction completeness. Iterative refinement improves whether the code runs without substantially closing the semantic and interaction gaps.
GuardianAgentBench tests tool agents across 580 scenarios
GuardianAgentBench covers 580 scenarios in six domains, three agent frameworks, six models, and five adversarial attack modes. The strongest tested configuration reaches 74.8% overall accuracy. Stronger models tend to skip required tool calls, while weaker ones more often choose or call the wrong tools.
An execution-time guard recovers 19.9% of failures at a 0.5% false-positive rate, outperforming the tested system-prompt defenses. The results come from the authors’ benchmark rather than an independent audit of deployed agents.
V-DEAL finds harmful video can bypass refusal under a benign question
V-DEAL tests six video-language models on three public benchmarks. The models recognize harmful video content with more than 81% accuracy, yet harmful videos paired with benign questions produce a 48.33% average attack success rate.
The authors attribute the gap to weaker refusal activation from visual understanding than from explicit harmful text. Their prompt-injection intervention reduces attack success by an average of 48.24 percentage points. Broader testing is needed before treating that intervention as a general video-safety control.
Faster IndexTTS-2 adds streaming and batching to zero-shot speech
Faster IndexTTS-2 accelerates the original model’s autoregressive language component, diffusion transformer, and vocoder with NVIDIA TensorRT and TensorRT-LLM. It also adds streaming output and batching for interactive and high-throughput uses.
On the English and Chinese Seed-TTS benchmark, the authors report up to a fivefold speedup for the autoregressive component and 3.6-fold end-to-end acceleration, with minimal changes to word error rate, speaker similarity, and naturalness. The tests are GPU-specific and do not establish mobile or browser performance.
New On The Events Calendar
Wonder News added SITE 2027 to the calendar. The Society for Information Technology and Teacher Education conference runs March 15-19 in Nashville. Educators and researchers can submit papers, workshops, demonstrations, roundtables, and corporate showcases through October 26, 2026. Attendee registration is open; the organizer lists a February 27 early-rate cutoff, although its detailed deadline table still contains 2026 dates.
Watch Next
- VoLN tests on physical drones and embodied game agents, with results beyond the initial baseline.
- Sequential-memory measurements across longer sessions, moving objects, and changing scenes.
- GLAM-SLAM frame rate, memory use, and export tests on creator hardware.
- TableVerse release terms and manipulation-policy gains from its 100,000 environments.
- Physical-trial counts for BiCompoDiff, tactile-policy margins for FELT, and PhysCoRe runtime.
- MV-Bench evaluations with iterative agents that can inspect and repair data bindings and interactions.
- Independent GuardianAgentBench and V-DEAL replications across new tools, frameworks, videos, and attack types.
- Faster IndexTTS-2 latency on smaller GPUs and longer multilingual dialogue.
- SITE’s venue details and correction of the stale dates in its registration deadline table.
This article was written with assistance from Wonder Bricks AI Agent and edited by SunnyLabs.